Fashion is a hard category to test well. Catalogs turn over every few weeks. Sizes and colors split one product into dozens of variants. Return rates are high, and the season changes who your visitors are. Any of these can quietly ruin an experiment.
This post lists the mistakes that show up most often in apparel and footwear stores, explains why each one distorts results, and shows what to do instead. Some of it is statistics, but none of it needs a math degree.
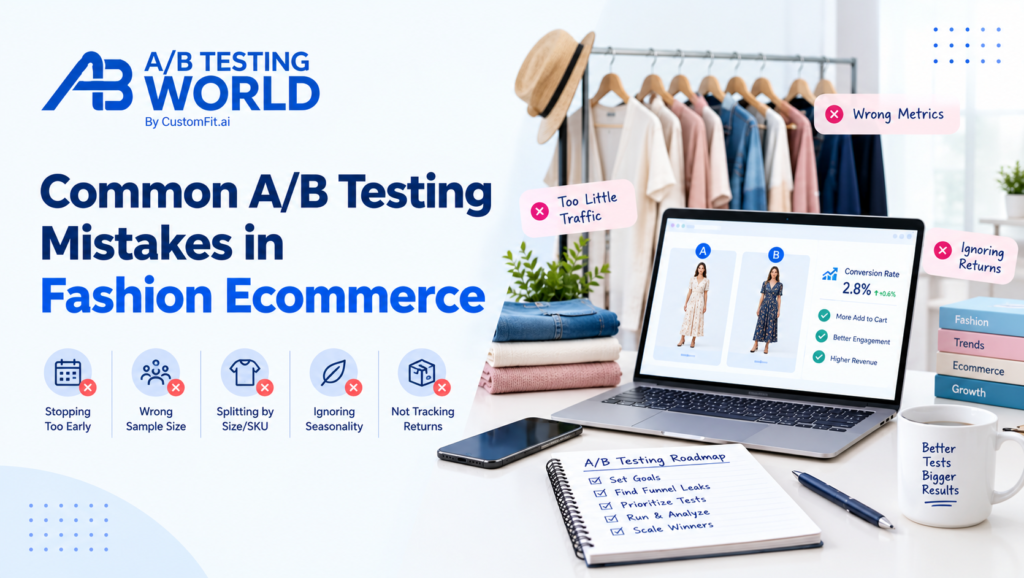
1. Calling the test too early
This is the most common mistake in any category, and fashion makes it worse because teams are always in a hurry before the next drop.
Here is the problem. If you check results every day and stop the moment one variant looks significant, you are running many tests, not one. Each look is another chance for random noise to cross the threshold. The false positive rate you actually get is well above the 5% you thought you chose.
What to do: Decide the sample size and the end date before launch. Don’t make a call before both are reached. If you need to monitor results as they come in, use a method designed for it (sequential testing or a Bayesian approach with a pre-set decision rule), not a standard fixed-sample test read over and over.
2. Starting without a sample size
“Run it for two weeks” isn’t a plan if your traffic can’t support it. The required sample depends on three things: your baseline conversion rate, the smallest lift you care about and how much risk of error you accept.
Some examples, at a 5% false positive rate and 80% power:
| Baseline conversion | Lift to detect (relative) | Visitors needed per variant |
| 2% | 10% | about 80,700 |
| 3% | 10% | about 53,200 |
| 3% | 20% | about 13,900 |
| 5% | 20% | about 8,200 |
A store converting at 2% that wants to detect a 10% relative lift (2.0% to 2.2%) needs roughly 160,000 visitors in total across both versions. If a product page gets 5,000 visits a month, that test will never finish.
What to do: Run the calculation first. If the number is out of reach, test a bigger change, test on a page with more traffic, or measure an earlier step in the funnel (like add to cart) where rates are higher.
3. Splitting traffic by size or by SKU
Fashion products have many variants. A single dress can come in six sizes and four colors. Teams sometimes run a test on a single variant page, or analyze results by size, and wonder why nothing is significant.
The traffic that lands on one color and size of one dress is tiny. Splitting an already small sample into many groups leaves each one too thin to read.
What to do: Run the test at the product level or the template level. Test all dresses together, or all product pages in a category, so the combined traffic is large enough. Analyze by size only as a follow-up question, not the main result.
4. Testing the product page one item at a time
A related mistake: running a separate test on each product, getting a handful of small, noisy results and treating them as findings.
If you change the layout of a product page, that change applies to every product. Testing it on a single best seller tells you about that product, and maybe not about your catalog.
What to do: Apply template tests to a group of products and compare them against a control group of similar products. Record which categories were included, because a result for dresses may not carry over to accessories.
5. Ignoring seasonality and drops
Fashion traffic isn’t stable. A new collection, a sale, a holiday, a heat wave, a social media post going viral. Each one changes who visits and what they want. If variant A ran during a quiet week and variant B ran during a sale, you didn’t run an A/B test.
This is why proper A/B testing runs both variants at the same time, with visitors randomly assigned. But even then, the period matters. A winning variant during a clearance sale may not win at full price.
What to do:
- Always run variants simultaneously, never one after the other.
- Run at least two full weeks, so weekday and weekend behavior are both included. Round up to full weeks.
- Avoid ending tests during major promotions, or analyze the promotion period separately.
- Keep a calendar of drops, sales and campaigns beside your test log.
Put Cleaner Testing Into Practice
Take the checklist to your own fashion store and run your next test properly. Use every CustomFit.ai feature free for 14 days.
6. Measuring conversion and ignoring returns
Fashion returns are expensive. A change that increases conversion can still lose money if it also increases returns. For example, a bold “free returns” banner or a model photo that flatters the product may push up orders and push up sends-back too.
Conversion rate is also a “fast” metric, and returns are a “slow” one. They arrive days or weeks after the order.
What to do: Choose a main metric that reflects profit more closely, such as revenue per visitor net of returns, or at least track return rate for each variant. Wait long enough after the test ends for returns to come in, and compare the variants again. Treat return rate as a guardrail, meaning a metric you don’t let get worse.
Read more: Why A/B Testing Is the Cheapest Growth Lever Most Brands Ignore
7. Randomizing at the wrong level
You have to decide what the unit of randomization is: the visitor, the session or the page view. If you randomize by page view, one shopper can see variant A on one page and variant B on the next. If you randomize by session, a shopper who returns the next day might get a different experience.
Fashion shoppers often take several visits to decide, and often switch between phone and laptop. A test that flips them between variants contaminates both groups.
What to do: Randomize at the visitor level using a persistent identifier (a first-party cookie or login) and keep the assignment consistent. Be aware that cross-device shoppers can still land in different groups unless you assign by logged-in user. Note this as a limitation.
8. Not checking for sample ratio mismatch
If you set a 50/50 split and the groups come out as 10,000 and 10,400 visitors, that may look close enough. It isn’t. A chi-square test on those counts gives a p-value of about 0.005. That kind of imbalance almost never happens by chance, and it means something in the setup is broken.
Common causes are a variant that loads slowly so some visitors leave before being counted, bot traffic that hits one version more, redirects that drop users, or caching that serves one version more often.
What to do: Run a sample ratio mismatch check on every test. If it fails, don’t trust the results. Find the cause, fix it and restart. Many testing tools have a built-in check; if yours doesn’t, the calculation is a simple one.
9. Changing several things at once, then claiming to know what worked
A redesigned product page might change the image gallery, the size selector, the description and the button all at once. If it wins, you have a better page, but you don’t know which change did the work. If it loses, you don’t know which change did the harm.
What to do: For learning, change one thing. For a full redesign, treat it as one test of the whole design and don’t attribute the result to a single element. If you really want to learn about multiple elements, use a multivariate design, and recognize that it needs far more traffic.
10. Looking at too many metrics and segments
If you check ten metrics across five segments, that’s fifty comparisons. At a 5% threshold you’d expect two or three to look significant by chance alone. Teams then pick the one that looks good and report it.
What to do: Name one primary metric and a short list of guardrails before launch. Treat everything else as exploratory, to be checked with a follow-up test. If you run many comparisons, apply a correction (such as Bonferroni or controlling the false discovery rate) or at least be more strict about what counts.
11. Trusting a lift without looking at the interval
A report that says “variant B won by 12%” hides the uncertainty. With limited traffic, the true lift might be anywhere from 1% to 23%. That’s a very different decision than a tight range around 12%.
What to do: Look at the confidence interval (or credible interval), not just the point estimate. If the interval includes lifts too small to matter, say so. Also, selected winners tend to overstate the real effect (the “winner’s curse”).
12. Treating revenue like a well-behaved number
Conversion rate is a yes/no outcome. Revenue per visitor isn’t. Most visitors spend nothing and a few spend a lot, with an occasional huge order. A single large order can swing the average of a variant by a surprising amount.
What to do: Look at the distribution, not only the mean. Consider capping extreme values at a high percentile (for instance the 99th) before comparing, and say that you did it. Use methods that suit skewed data, like a bootstrap, instead of assuming a normal distribution. Keep conversion rate and average order value as separate lines so you can see which one moved.
13. Letting the test break the page
A testing script that delays rendering can flash the original page before the variant appears, and a heavier variant can load slower. On mobile, where most fashion traffic arrives, a half-second delay can cut conversion by itself.
What to do: Check each variant on real phones over a normal connection, and compare load time between versions. If one is slower, you’re testing speed as well as design.
Test Without the Guesswork
Launch your next fashion test with a clear plan. Try CustomFit.ai free for 14 days, cancel anytime.
A pre-launch checklist
- One clear hypothesis
- One primary metric and named guardrails (including returns)
- Sample size calculated and end date fixed
- Randomization at the visitor level
- Variants run at the same time
- Both variants checked on real phones
- Sample ratio check planned
- No major promotion overlapping the test
- Audience, dates and conditions recorded next to the result
- Analysis plan written down before looking at results
Summary
Most fashion testing problems come from three sources: too little traffic for the question, a calendar that keeps changing the audience and a metric (conversion) that ignores the biggest cost in the category, which is returns. Fix those three and many of the other mistakes become easier to avoid.
FAQs
Why do returns matter in A/B testing for fashion?
Because a change can raise orders and also raise returns, leaving profit lower. Track return rate for each variant, and wait long enough after the test for returns to arrive before making the final call.
What is sample ratio mismatch?
When there is a deviation in the number of people visiting each segment from an anticipated split based on the percentage assigned. In this case, abnormal deviation points to technical issues that could include problems such as Site loading speed, bot traffic, and redirection, thus showing that the outcome is not trustworthy until the issues are fixed.
How long should an A/B test run on a fashion store?
Long enough to reach the sample size you calculated, and at least two full weeks so weekday and weekend patterns are included. If your traffic is low, it may take longer, or you may need to test something bigger or earlier in the funnel.
Can I test during a sale?
You can, but the result only describes sales behavior. Visitors during a sale are different from your usual traffic, so a winner may not hold at full price. Analyze sale periods separately from normal ones.